AWK and Regex Linux Guide: Practical Commands and Examples
I use tools like these constantly when working with Nmap results, Linux logs, service output, IP address lists, and troubleshooting data. A simple one-line command can often replace several minutes of manually searching through a file.
This guide collects the AWK and regex commands I am most likely to need again, with practical examples that can be copied, modified, and reused.
AWK and Regex Linux Guide: The Basic Idea
The easiest way I have found to think about these tools is:
Regex asks: What text matches this pattern?
AWK asks: Once I find the line, which fields do I want, and what should I do with them?
They become especially useful when combined.
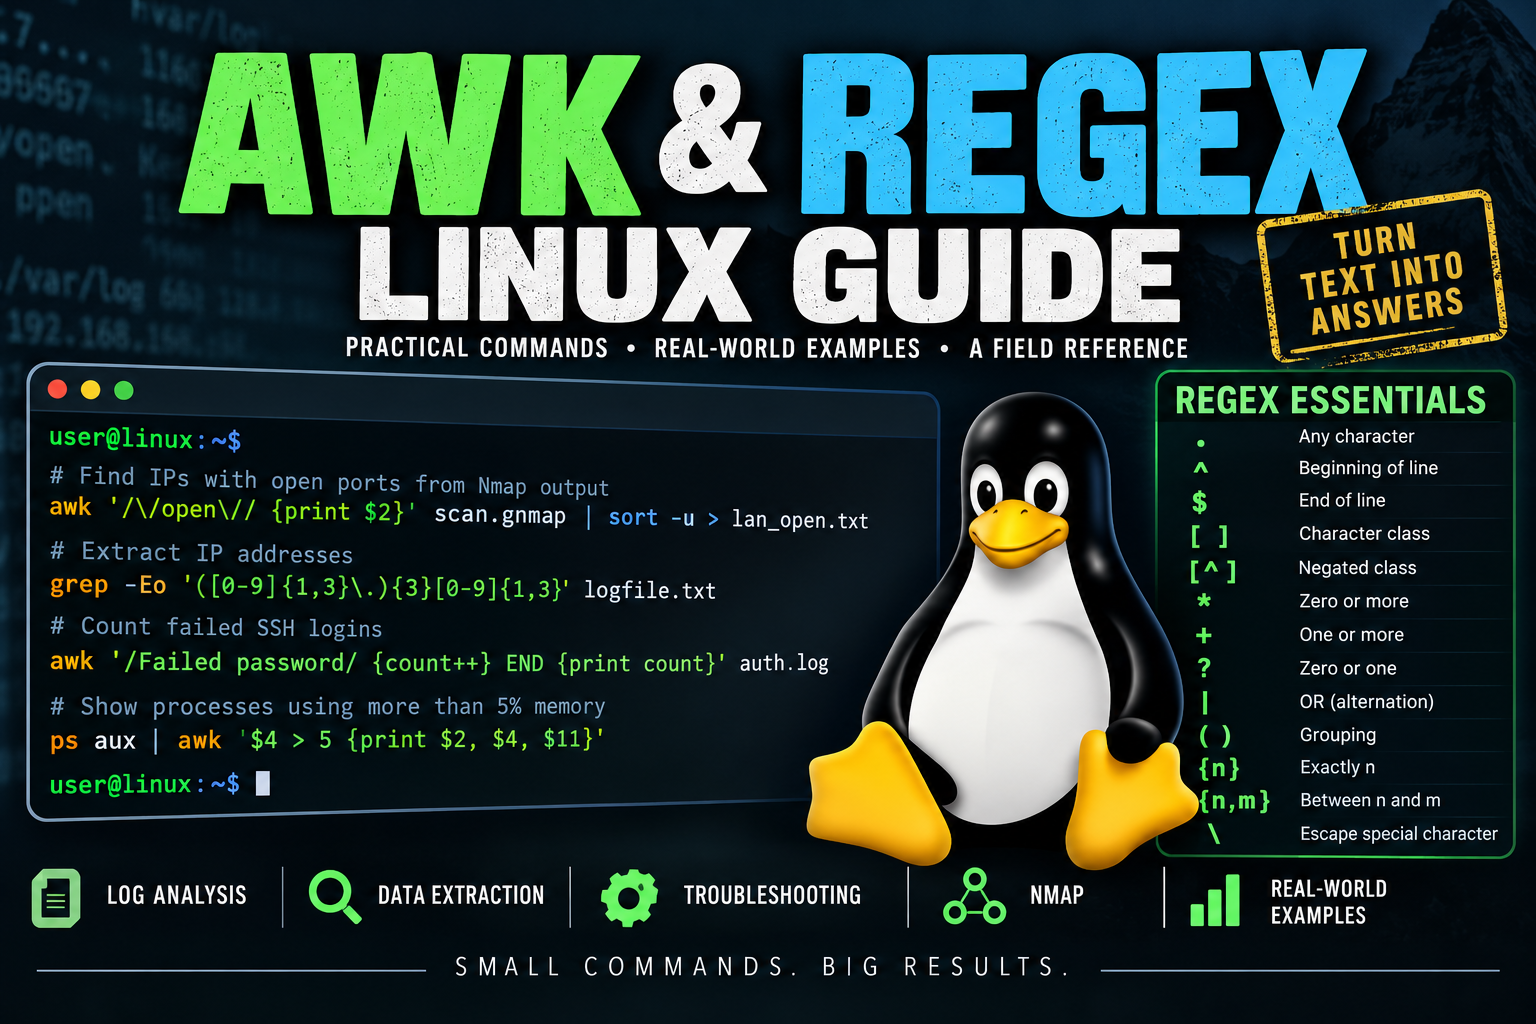
For example, this command extracts IP addresses from Nmap greppable output when the host has an open port:
awk '/\/open\// {print $2}' lan_scan.gnmapThe command breaks down like this:
/\/open\//     Find lines containing /open/
{print $2}     Print the second field
Basic Regular Expressions
Literal Text
The simplest regular expression is just the text you want to find.
errorUsing grep:
grep 'error' logfile.txtFor a case-insensitive search:
grep -i 'error' logfile.txt. — Any Character
A period in a regular expression means any single character.
c.tThis could match:
cat
cut
c9t
c-t
To match an actual period, escape it with a backslash:
\.For example:
192\.168\.^ — Beginning of Line
The caret matches the beginning of a line.
^HostThis matches:
Host: 192.168.123.10But not:
Nmap Host: 192.168.123.10Example:
grep '^Host' scan.gnmap$ — End of Line
The dollar sign matches the end of a line.
failed$This matches:
authentication failedBut not:
authentication failed again[ ] — Character Classes
Square brackets let you match one character from a group.
[abc]This matches:
a
b
c
To match a digit:
[0-9]Example:
grep -E '[0-9]' file.txtTo match letters:
[A-Za-z][^ ] — Negated Character Class
When the caret appears inside square brackets, it means anything except the listed characters.
[^0-9]This means anything except a digit.
Regex Repetition
Several characters control how many times something may appear.
| Expression | Meaning |
|---|---|
| * | Zero or more |
| + | One or more |
| ? | Zero or one |
| {3} | Exactly three |
| {2,5} | Between two and five |
| {2,} | At least two |
For example:
[0-9]+This means one or more digits.
grep -E '[0-9]+' file.txtRegex Alternatives
| — OR
The pipe character means OR.
error|warning|criticalExample:
grep -Ei 'error|warning|critical' /var/log/syslogThis is particularly useful when reviewing logs.
Regex Grouping
Parentheses group parts of an expression together.
(error|warning|critical)Another example:
grep -Ei '(failed|denied|invalid) password' auth.logThis can match phrases such as:
failed password
denied password
invalid password
Useful Regex Patterns
IPv4 Address
A practical pattern for extracting IPv4-looking addresses is:
([0-9]{1,3}\.){3}[0-9]{1,3}Example:
grep -Eo '([0-9]{1,3}\.){3}[0-9]{1,3}' logfile.txtThe -o option tells grep to print only the matching portion.
This is useful for extraction, but it is not strict IP address validation. It can still match something such as 999.999.999.999.
MAC Address
([0-9A-Fa-f]{2}:){5}[0-9A-Fa-f]{2}Example:
grep -Eo '([0-9A-Fa-f]{2}:){5}[0-9A-Fa-f]{2}' file.txtEmail Address
[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}Example:
grep -Eo '[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}' file.txtRegex Escaping
Several characters have special meanings in regular expressions:
. * + ? [ ] ( ) { } ^ $ | \If you need to search for one of these characters literally, you normally escape it with a backslash.
For example:
192\.168\.123\.118Using AWK:
awk '/192\.168\.123\.118/' logfile.txtThe Nmap example is slightly more interesting:
awk '/\/open\//' scan.gnmapThe actual text being searched for is:
/open/But AWK also uses forward slashes to surround a regular expression:
/regex/So the literal forward slashes must be escaped:
\/open\/AWK Command Basics
The basic structure of an AWK command is:
awk 'pattern { action }' fileFor example:
awk '/error/ {print}' logfile.txtThis means:
Find lines containing error and print those lines.
Understanding AWK Fields
AWK automatically divides a line into fields based on whitespace.
Given this line:
192.168.123.118 443 open httpsAWK sees:
$1 = 192.168.123.118
$2 = 443
$3 = open
$4 = https
Print the first field:
awk '{print $1}' file.txtPrint the port and service:
awk '{print $2, $4}' file.txtUseful AWK Variables
| Variable | Meaning |
|---|---|
| $0 | The entire line |
| $1 | First field |
| $2 | Second field |
| $NF | Last field |
| NF | Number of fields |
| NR | Current line number |
| FNR | Line number within the current file |
| FS | Input field separator |
| OFS | Output field separator |
Example:
awk '{print NR, $1}' file.txtPossible output:
1 192.168.123.1
2 192.168.123.3
3 192.168.123.118
Selecting Fields with AWK
Print the first field:
awk '{print $1}' file.txtPrint the first and third fields:
awk '{print $1, $3}' file.txtPrint the last field:
awk '{print $NF}' file.txtPrint the number of fields:
awk '{print NF}' file.txtAWK Field Separators
By default, AWK separates fields using whitespace.
For colon-separated files such as /etc/passwd, use:
awk -F: '{print $1}' /etc/passwdExample output:
root
daemon
www-data
bwright
Print the username and login shell:
awk -F: '{print $1, $7}' /etc/passwdSimple CSV Files
awk -F',' '{print $1, $3}' file.csvThis works well for simple CSV files. If the file contains quoted commas or complex formatting, a dedicated CSV parser is usually safer.
Filtering Numeric Values with AWK
Suppose a file contains:
server1 25
server2 90
server3 75
Find values greater than 80:
awk '$2 > 80 {print}' file.txtOutput:
server2 90Multiple AWK Conditions
Use && for AND:
awk '$2 > 80 && $3 == "open" {print}' fileUse || for OR:
awk '$3 == "open" || $3 == "filtered" {print}' fileUse != for NOT EQUAL:
awk '$3 != "closed" {print}' fileRegex Against Specific AWK Fields
Use the tilde operator to test a field against a regular expression:
awk '$3 ~ /open/' fileTo find fields that do not match:
awk '$3 !~ /closed/' fileExact AWK Comparison vs Regex
These two commands look similar but behave differently.
Exact comparison:
awk '$3 == "open"' fileRegex comparison:
awk '$3 ~ /open/' fileThe second version could potentially match:
open
opened
reopened
AWK BEGIN and END
AWK can perform actions before or after processing a file.
Run something before processing:
awk 'BEGIN {print "Starting"} {print $1}' fileRun something after processing:
awk '{count++} END {print count}' fileA quick way to count lines is:
awk 'END {print NR}' fileCounting Matches with AWK
Count failed SSH login attempts:
awk '/Failed password/ {count++} END {print count}' /var/log/auth.logThis is useful when reviewing authentication logs during troubleshooting or incident analysis.
Count Occurrences by Value
A very common Linux pattern is to extract values, sort them, count duplicates, and then sort by frequency.
For example:
awk '/Failed password/ {print $(NF-3)}' /var/log/auth.log |
sort |
uniq -c |
sort -nr
Possible output:
142 185.220.101.32
87 45.33.22.10
14 192.168.123.50
This type of pipeline is worth remembering.
Using sort and uniq
Remove duplicate lines:
sort -u file.txtCount duplicate values:
sort file.txt | uniq -cSort the highest counts first:
sort file.txt | uniq -c | sort -nrGrep and AWK Together
You may sometimes see:
grep 'open' scan.txt | awk '{print $2}'But AWK can usually perform both operations:
awk '/open/ {print $2}' scan.txtI generally prefer the AWK-only version when the command remains easy to read.
AWK and Regex Linux Guide for Nmap Output
Nmap greppable output is a good example of where AWK and regular expressions become extremely useful.
To find hosts that have at least one open port:
awk '/\/open\// {print $2}' lan_scan.gnmapTo remove duplicate IP addresses:
awk '/\/open\// {print $2}' lan_scan.gnmap | sort -uTo save those IP addresses into a file:
awk '/\/open\// {print $2}' lan_scan.gnmap |
sort -u > lan_open.txt
That file can then be passed directly back to Nmap:
nmap -iL lan_open.txtFor a more detailed follow-up scan:
sudo nmap -sS -sV -O -iL lan_open.txt -oA lan_detailedExtracting Hosts Marked Up by Nmap
A greppable Nmap discovery scan may contain lines such as:
Host: 192.168.123.1 () Status: Up
Host: 192.168.123.3 () Status: Up
Host: 192.168.123.65 () Status: Up
Extract the IP addresses:
awk '/Status: Up/ {print $2}' scan.gnmapSave them into another file:
awk '/Status: Up/ {print $2}' scan.gnmap > alive.txtAWK and Regex for Linux Log Analysis
SSH Login Failures
grep 'Failed password' /var/log/auth.logOr using AWK:
awk '/Failed password/' /var/log/auth.logSuccessful SSH Logins
awk '/Accepted password|Accepted publickey/' /var/log/auth.logMultiple Severity Levels
awk '/ERROR|WARNING|CRITICAL/' application.logCase-Insensitive AWK Search
awk 'tolower($0) ~ /error/' logfile.txtApache and Nginx Log Analysis
A typical web access log may contain something similar to:
192.168.1.50 - - [14/Sep/2026:10:00:01] "GET /login HTTP/1.1" 200 4312Extract client IP addresses:
awk '{print $1}' access.logCount requests by IP address:
awk '{print $1}' access.log |
sort |
uniq -c |
sort -nr
Show the top ten:
awk '{print $1}' access.log |
sort |
uniq -c |
sort -nr |
head
This can be useful when looking for scanners, brute-force attempts, or unusually active clients.
HTTP Status Code Analysis
For a standard Apache combined log format, count status codes:
awk '{print $9}' access.log |
sort |
uniq -c |
sort -nr
Find 404 responses:
awk '$9 == 404 {print}' access.logFind server errors:
awk '$9 >= 500 {print}' access.logProcess Analysis with AWK
To show processes using more than five percent memory:
ps aux | awk '$4 > 5 {print $2, $4, $11}'In standard ps aux output:
$2  PID
$4  Memory percentage
$11 Command
Disk Usage with AWK
Start with:
df -hShow filesystems above 80 percent utilization:
df -h |
awk 'NR > 1 && $5+0 > 80 {print}'
The $5+0 trick converts something such as:
87%into a numeric value AWK can compare.
Network Connection Analysis
View current network connections:
ss -tunapAn AWK filter could look like:
ss -tunap |
awk '$1 == "tcp" && $2 == "ESTAB"'
The exact field positions used by ss can vary by version and options, so it is always worth looking at the output before writing a field-specific AWK command.
AWK Variables and Calculations
AWK can also perform arithmetic.
Add values from the second field:
awk '{total += $2} END {print total}' numbers.txtCalculate an average:
awk '{sum += $2; count++} END {print sum/count}' numbers.txtCreating Custom Output with AWK
AWK can turn raw data into more readable output.
awk '{print "IP:", $1, "Port:", $2}' file.txtPossible output:
IP: 192.168.123.118 Port: 443Using printf with AWK
For cleaner formatting, use printf:
awk '{printf "%-16s %-8s %-10s\n", $1, $2, $3}' filePossible output:
192.168.123.3    389      open
192.168.123.118  443      open
192.168.123.107  8006     open
This is useful when turning command output into a quick report.
AWK if Statements
AWK can also use regular programming logic.
awk '{
    if ($3 == "open")
        print $1, $2
}' file
Another example:
awk '{
    if ($5 > 80)
        print "WARNING:", $0
}' file
Multiple AWK Actions
AWK is more than a field extraction utility. It is a small programming language.
awk '
/open/ {
    count++
    print $2
}
END {
    print "Open hosts:", count
}' scan.gnmap
The Linux Text Processing Pipeline
One command-line pattern I find useful to remember is:
command
|
filter
|
extract
|
sort
|
count
For example:
cat auth.log |
grep 'Failed password' |
awk '{print $(NF-3)}' |
sort |
uniq -c |
sort -nr
The unnecessary cat can be removed:
awk '/Failed password/ {print $(NF-3)}' auth.log |
sort |
uniq -c |
sort -nr
The second version is shorter and easier to read.
Commands Worth Remembering
| Goal | Command |
|---|---|
| Match text | grep 'text' file |
| Extended regex | grep -E 'regex' file |
| Case-insensitive search | grep -i 'text' file |
| Show only matching text | grep -o 'regex' file |
| Extract a field | awk '{print $2}' file |
| Filter and extract | awk '/regex/ {print $2}' file |
| Remove duplicates | sort -u |
| Count duplicates | sort | uniq -c |
| Highest count first | sort | uniq -c | sort -nr |
| First ten lines | head |
| Last ten lines | tail |
| Count lines | wc -l |
| Replace text | sed 's/old/new/g' |
Five AWK Patterns Worth Memorizing
1. Extract a field:
awk '{print $1}' file2. Find matching lines:
awk '/pattern/ {print}' file3. Find a pattern and extract a field:
awk '/pattern/ {print $2}' file4. Filter based on a field:
awk '$3 == "open" {print $1}' file5. Count occurrences:
awk '{print $1}' file | sort | uniq -c | sort -nrThose five commands alone cover a surprising amount of day-to-day Linux administration and troubleshooting.
My Shortcut for Remembering AWK
I find it easiest to think of an AWK command as:
WHERE        WHAT
/condition/  {action}
For example:
awk '/\/open\// {print $2}' scan.gnmapThat can almost be read as plain English:
Where /open/ appears, print field two.
Once I started thinking about AWK that way, I stopped trying to memorize complete commands. Instead, I could look at the data, decide what I wanted to match, determine which field contained the information I needed, and build the command from there.
That is really where AWK and regular expressions become useful. They are not commands I need to memorize perfectly. They are tools I can combine when I need to turn a pile of command-line output into the few pieces of information I actually care about.